AI Safety Camp
Published:

Mechanistic Interpretability Via Learning Differential Equations
Mechanistic interpretability aims to uncover the mechanisms through which a neural network model makes predictions. We investigated a transformer model that learned differential equations, namely ODEFormer, hoping that anything we learned on this medium complexity example might transfer to large language models. Several techniques from mechanistic interpretability were combined to learn how this model makes predictions.
I developed a streamlit app that can be used to investigate the activation patterns throughout the network. With this, we found a few noteworthy patterns, such as an odd attention pattern seen in the figure below.
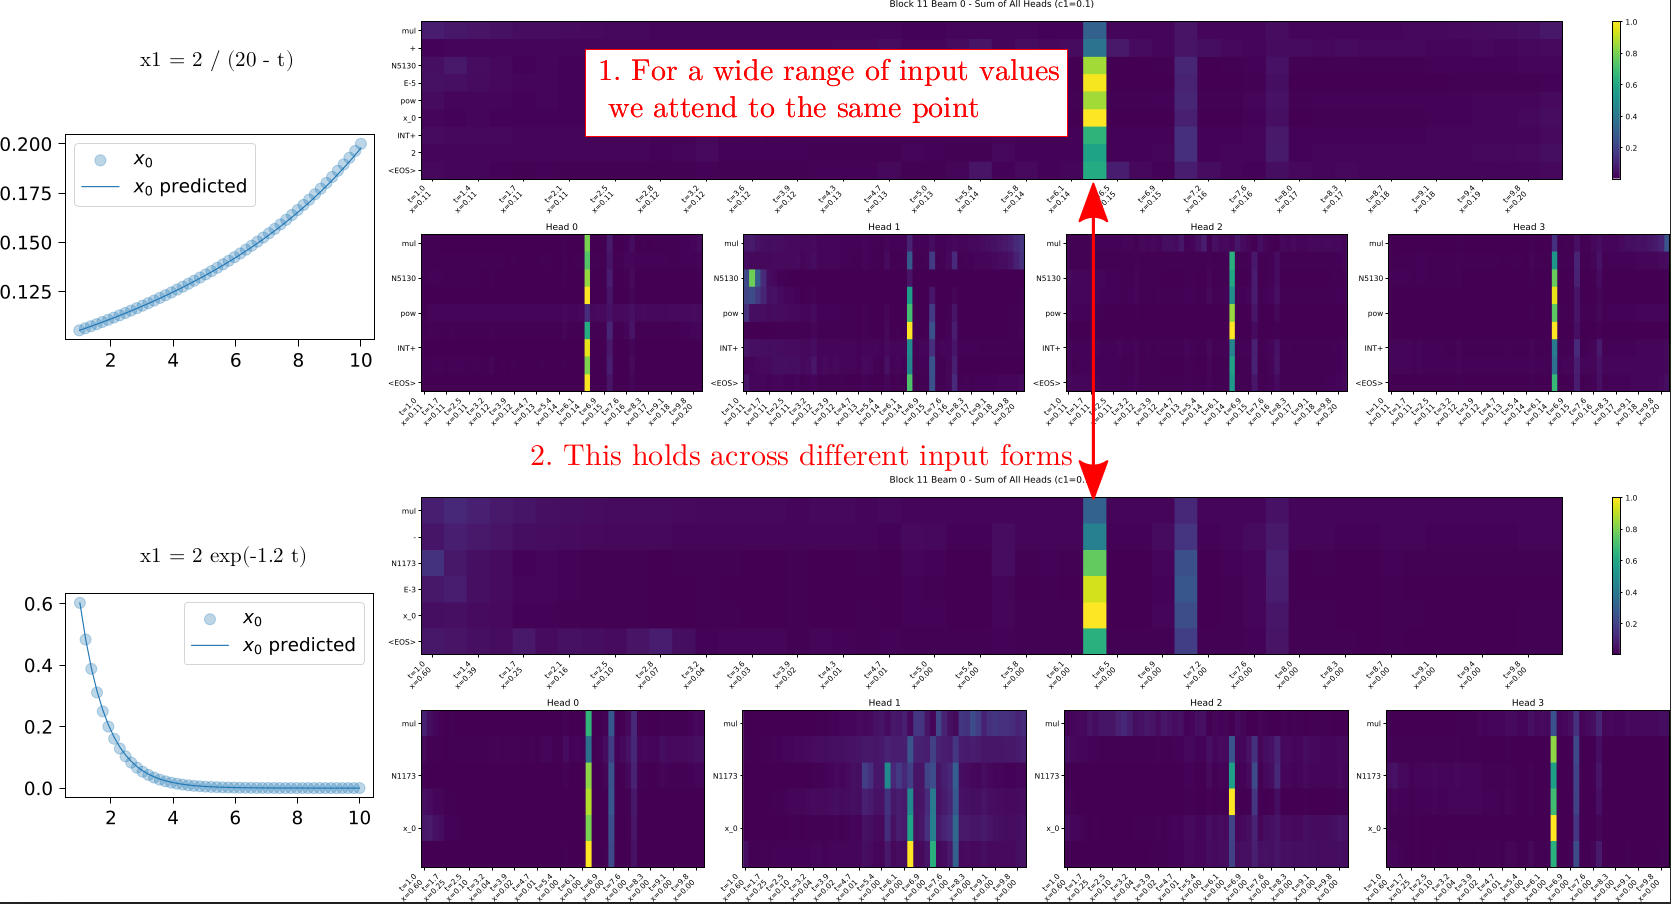
This token was encoded differently compared to the other tokens.
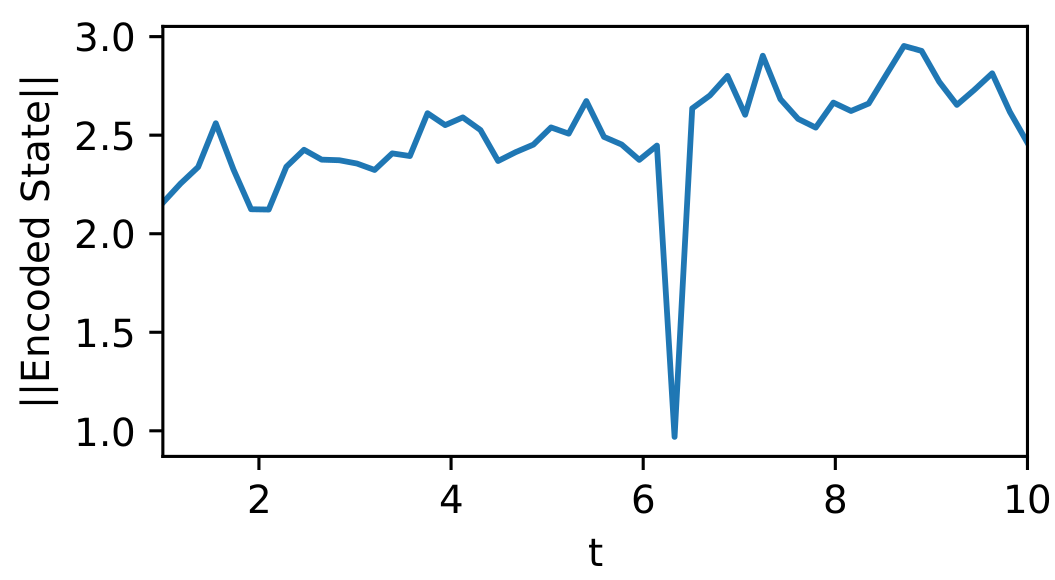
This is one of the anomalies that allowed other teams to dive deeper into what causes this behavior.
Here is a blogpost written with more information.